Built for GPUs. Lossless. Non-blocking.
September 29, 2026 · SpineRail engineering
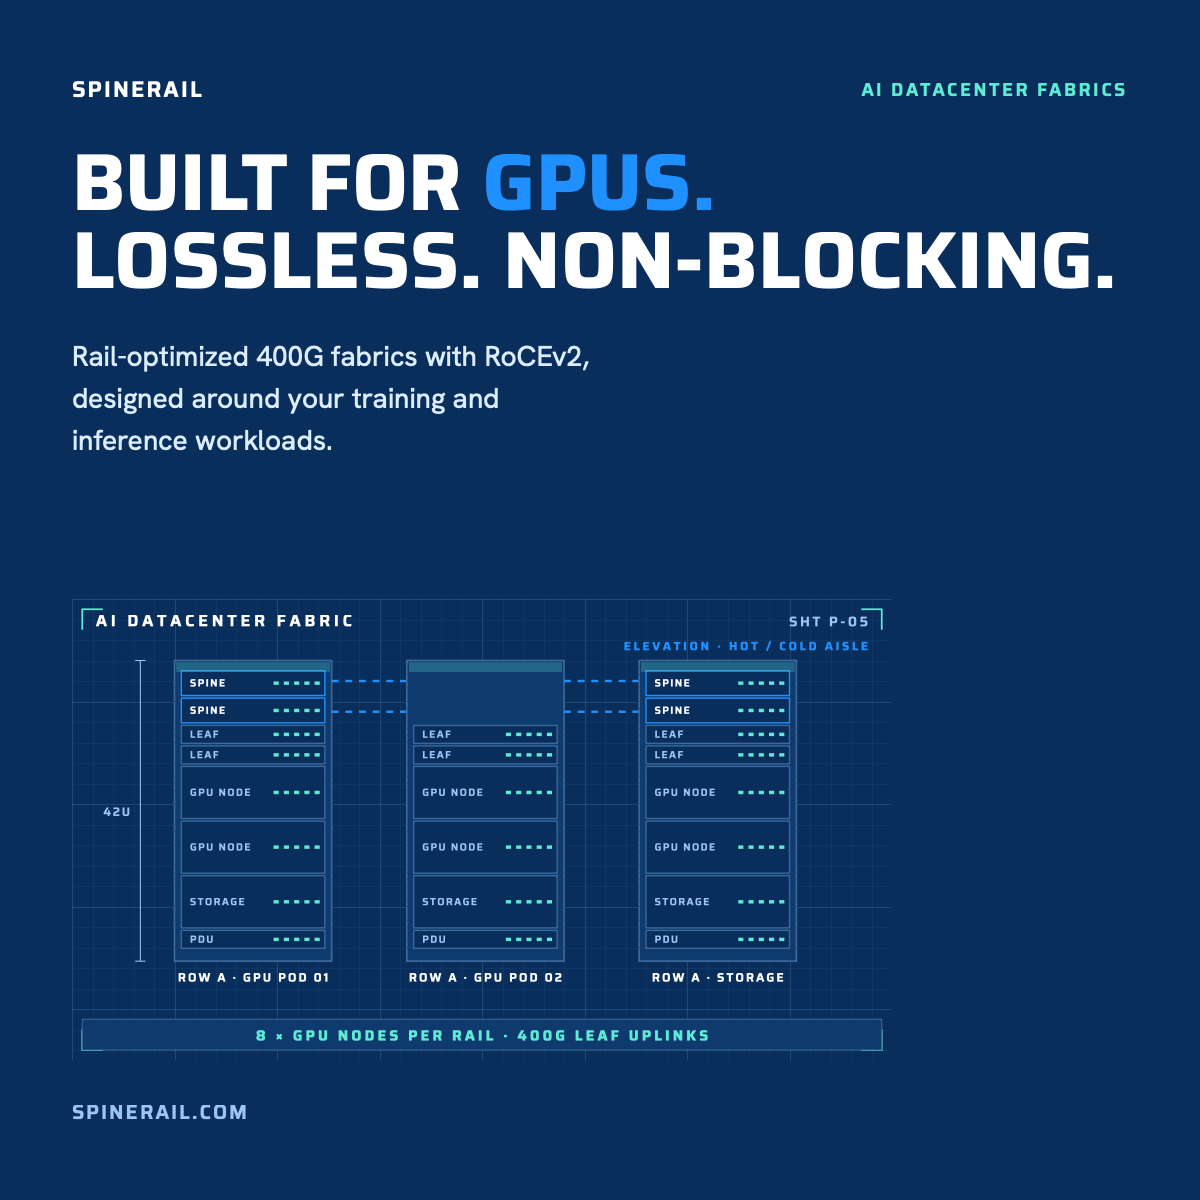
GPU clusters punish ordinary network design. Collective operations saturate every link at once, a single congested path slows the whole job, and packet loss that an enterprise application never notices will stall training. The fabric has to be lossless and non-blocking, and it has to be tuned for the specific traffic pattern of the workload.
We build rail-optimized leaf-spine fabrics at 400G and 800G on Ethernet with RoCEv2. Priority flow control, ECN marking and congestion-control parameters are set per platform and proven on the twin, buffer profiles are chosen for the collective sizes you actually run, and separate fabrics carry storage and management traffic so nothing competes with the GPUs.
Handover is a number, not a document: NCCL all-reduce and all-to-all benchmarks across the full cluster against the theoretical bandwidth, with the results and the configuration repository yours to keep.